Most read
Fifty articles that get opened more often than the rest.
 YuE: audio generator — what it does and what you need to run itYuE is an open source audio generator from the M-A-P team, which the authors describe as a model for creating full songs. According to the developers…
 OpenVoice: audio generator — what it does and what you need to run itOpenVoice is an open source speech generator from the MyShell team. It handles the text-to-speech task and, as described by the authors, belongs to th…
 SparsePR accelerates video generators with training-free sparse attentionResearchers introduced SparsePR, a training-free block-sparse attention method for video generators and world models. The paper was published on arXiv…
 HunyuanVideo gets a generation acceleration method with near-lossless quality at 5–7x speedupResearchers introduced LinCa, a method for accelerating diffusion models via learnable feature caching with component-wise decomposition. Instead of a…
 New h3-vbvr model on HuggingFace tackles image-to-videoOn August 18, 2026, the Patarapoom/h3-vbvr model was published on HuggingFace with the image-to-video task. At the time of publication, it had 2,434 d…
 MusicGen: audio generator — what it does and what you need to run itMusicGen is an audio generator from Meta that turns a text description into audio. It is part of the Audiocraft library and handles the text-to-audio…
 MOSS-SoundEffect without CUDA (Mac and AMD): audio generator — what it does and what you need to run itMOSS-SoundEffect without CUDA is a desktop application for generating sound effects from text descriptions. The build is aimed at Mac computers with A…
 KeyID introduces training-free method for identity-preserving video generationA paper on arXiv presents KeyID, a training-free framework for identity-preserving video generation that separates video dynamics synthesis from ident…
 AnyTalk generates 3D speech animation for arbitrary characters without animation dataResearchers introduced AnyTalk, a method for generating 3D speech animation for arbitrary characters that requires neither animation data nor manual r…
 Audio-visual generation gets an acceleration method that preserves audio-video synchronizationThe authors of the paper Efficient Audio-Visual Generation via Synchrony-Aware Cross-Modal Sparse Attention propose a method to speed up inference for…
 Qwen-Video-Edit turns an image editing model into a video editorAlibaba introduced Qwen-Video-Edit, an approach where the instruction-based image editing model Qwen-Image-Edit is applied to video without training a…
 MOSS-SoundEffect: audio generator — what it does and what you need to run itMOSS-SoundEffect is an open-source audio generator that turns a text description into audio. The model's task is text-to-audio: the user describes the…
 MMAudio: audio generator — what it does and what you need to run itMMAudio is an open source audio generator that synthesizes an audio track from video or a text description. The developers position it as a tool for h…
 MegaParts scales part-based 3D object generation to 300 partsResearchers introduced MegaParts, a framework for generating 3D objects decomposed into semantic parts. The approach is based on a vector-quantized to…
 V-RAE proposes a new approach to latent spaces for video generationA paper on V-RAE has been published on arXiv, in which the authors rethink the structure of video autoencoder latent spaces. Instead of optimizing the…
 Alaya-EVOKE presents a method for generating long interactive worlds with linear scalingA paper by Alaya-EVOKE has been published on arXiv, in which the authors tackle the task of generating long interactive worlds. They externalize the s…
 F5-TTS: audio generator — what it does and what you need to run itF5-TTS is an open source speech generator that turns text into sound. The project was created by developer SWivid and is distributed as code and ready…
 DiffRhythm: audio generator — what it does and what you need to run itDiffRhythm is an audio generator that, as described by the authors, is designed to create complete songs end-to-end, from text to finished audio, usin…
 LTX-2.5 released on HuggingFace with text-to-video taskThe model comfyicu/LTX-2.5 has been published on HuggingFace with the text-to-video task. Publication date: 13.08.2026, the model has 3630 downloads…
 LTX-2.5 text-to-video model released on HuggingFaceThe yuvraj108c/LTX-2.5 model with a text-to-video task has been published on HuggingFace. Publication date: August 12, 2026. As of this news note, the…
 News Note on a New Diffusion-Based Method for Removing Reflections from VideoResearchers presented the work From Synthesis to Removal: Physics-Grounded Reflection Simulation and Diffusion-Based Video Dereflection, published on…
 LTX-Video and CogVideoX Get a New Zero-Shot Captioning Method via Synthetic DataResearchers have published a paper on arXiv titled Watching Synthetic Videos: Aligning Cross-modal Representations with Visual Synthesis for Zero-shot…
 Minimax-H3-fl2va-ref2va-hybrid-models: new text-to-video model on HuggingFaceOn August 11, 2026, the model smhfacct/Minimax-H3-fl2va-ref2va-hybrid-models was published on HuggingFace with the text-to-video task. At the time of…
 CosyVoice: audio generator — what it does and what you need to run itCosyVoice is an open source speech generator from Alibaba. It tackles the text-to-speech task: converting text into spoken audio. The authors describe…
 ChatTTS: audio generator — what it does and what you need to run itChatTTS is an open source audio generator from the 2noise team. It tackles the text-to-audio task: converting text into speech geared toward everyday…
- Latent-to-4D generates 4D scenes directly from video latents without intermediate RGBThe authors of the paper Beyond Pixels: From Video Priors to 4D Worlds propose the Latent-to-4D method, which bypasses the RGB video reconstruction st…
 Sci-VBench: A Benchmark for Scientific Accuracy of Video from Generative ModelsThe authors of Sci-VBench introduced a benchmark for evaluating video generation in scientific domains. It includes 1,253 expert-annotated examples ac…
 Robust-WAM adds semantic robustness to World-Action Models built on video generatorsResearchers from arXiv presented Robust-WAM, a post-training method for World-Action Models built on video generative models. The main problem the wor…
 Vorch-Streamer turns avatar generation into real-time streaming videoarXiv has published Vorch-Streamer, a post-training method that enables real-time text-to-video generation with audio. The authors address two issues…
 HelloWorld — a model for social interaction with characters in video worldsResearchers have introduced HelloWorld, a video world model in which the user can interact with characters on screen. With the press of a button, the…
 Bark: audio generator — what it does and what you need to run itBark is an open source audio generator from Suno that tackles the text-to-speech task: it converts text into speech and other sounds based on a text d…
 VA-Judger: Reward Model for Joint Video and Audio GenerationResearchers introduced VA-Judger, a reward model for post-training of joint video and audio generation systems, along with the VAPref-10K dataset of 1…
- GVCCTurbo proposes bitrate planning for generative compression of video and images withoutarXiv Researchers introduced GVCCTurbo, a planner that separates costly updates of the generative prior from transmitting corrections through a codebo…
- SQuad accelerates video generation in Wan 2.2, reducing attention by 67xThe authors of SQuad introduced a sub-quadratic attention distillation method for Video Diffusion Transformers. Instead of training a model from scrat…
 SUV: Scene Future as Video Generation for End-to-End DrivingOn August 4, 2026, a paper on arXiv introduced SUV — an end-to-end driving framework that frames future scene understanding as a video generation task…
- SPADE accelerates attention in video diffusion transformers without fine-tuningResearchers have introduced SPADE, a sparse attention engine that accelerates inference of video diffusion transformers without model fine-tuning. The…
 Token Radius Attention Speeds Up Video Generation in Diffusion Transformers Without Fine-TuningResearchers from Peking University have introduced Token Radius Attention (TRA), a method that reduces the computational load in Video Diffusion Trans…
 ACE-Step: audio generator — what it does and what you need to run itACE-Step is an open source audio generator that turns a text description into audio. The developers position it as a step toward a base model for musi…
 VideoArgus offers a unified rubric-based evaluation system for video generation and editingResearchers have introduced VideoArgus, a framework for evaluating the quality of generated and edited videos, described in a paper on arXiv. Unlike e…
 EchoCache accelerates sound-driven video generation using audio signal energyarXiv reports on EchoCache, a caching method for audio-driven video generation (A2V). The authors identified two types of mismatch in existing approac…
 MAGI-2-preview by Sand AI: new open-source image-to-video model on HuggingFaceThe sand-ai/MAGI-2-preview model has been published on HuggingFace — a preview version of the image-to-video generator by Sand AI. The model handles t…
 UniMoCa unifies human motion and camera control in a single visual representationResearchers have introduced UniMoCa, a method that translates both human motion and camera trajectory into a shared visual representation called Motio…
 MoRoute proposes dynamic layer routing for multimodal video generationResearchers from MoRoute published a paper proposing to combine a frozen vision-language model (VLM) and a pretrained video diffusion transformer (DiT…
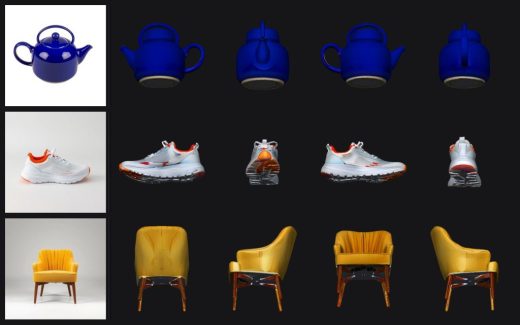 Hunyuan3D 2.1 without CUDA: update adds ROCm and PBR texturingThe port of Hunyuan3D 2.1 to hardware without CUDA was updated on August 9, 2026, and it now includes something that was previously missing entirely…
 FreqForcing extends autoregressive video generation to two minutes without fine-tuningOn July 29, 2026, the paper FreqForcing: Autoregressive Long Video Generation via Spectral Self-Anchoring appeared on arXiv. The authors investigate t…
- Wan: video generator — what it does and what you need to run itWan is an open source video generator from Alibaba that tackles the text-to-video task. The model converts a text description into a video sequence an…
 Rodin: 3D generator — what it does, formats, and rights to the resultRodin is a cloud-based 3D generator by Deemos, powered by the Gen-2 model. The service turns text descriptions or images into 3D assets without requir…
 ROAD cuts the cost of 3D generation training by transferring knowledge from discriminative modelsThe authors of ROAD: Reciprocal-Objective Alignment of Discriminative Semantics for 3D Shape Generation propose a method that uses discriminative 3D m…
 Stream4D adds 4D consistency to streaming autoregressive video modelsThe authors of the paper Stream4D: 4D-Consistency for Streaming Autoregressive Diffusion Video Models (arXiv, 20.08.2026) propose a training method fo…
 ES3D adds component-level 3D editing via semantic embeddingsA paper on ES3D — a framework for component-level editing of 3D assets — has been published on arXiv. The authors propose embedding semantics directly…